The Cost of Manufacturing Downtime: Hidden Costs, Profit Impact & How to Reduce Them

Manufacturing downtime costs more than the minutes a machine sits idle. A production stop can reduce output, leave employees waiting, trigger emergency maintenance, create scrap or rework, require overtime to recover production, delay shipments, and consume capacity that could have been used more profitably.

The true cost of manufacturing downtime is the value of production that cannot be recovered, plus the additional costs created by the interruption. That can include repair and maintenance expenses, labor inefficiency, overtime, scrap, rework, expedited shipping, penalties, and other recovery costs.
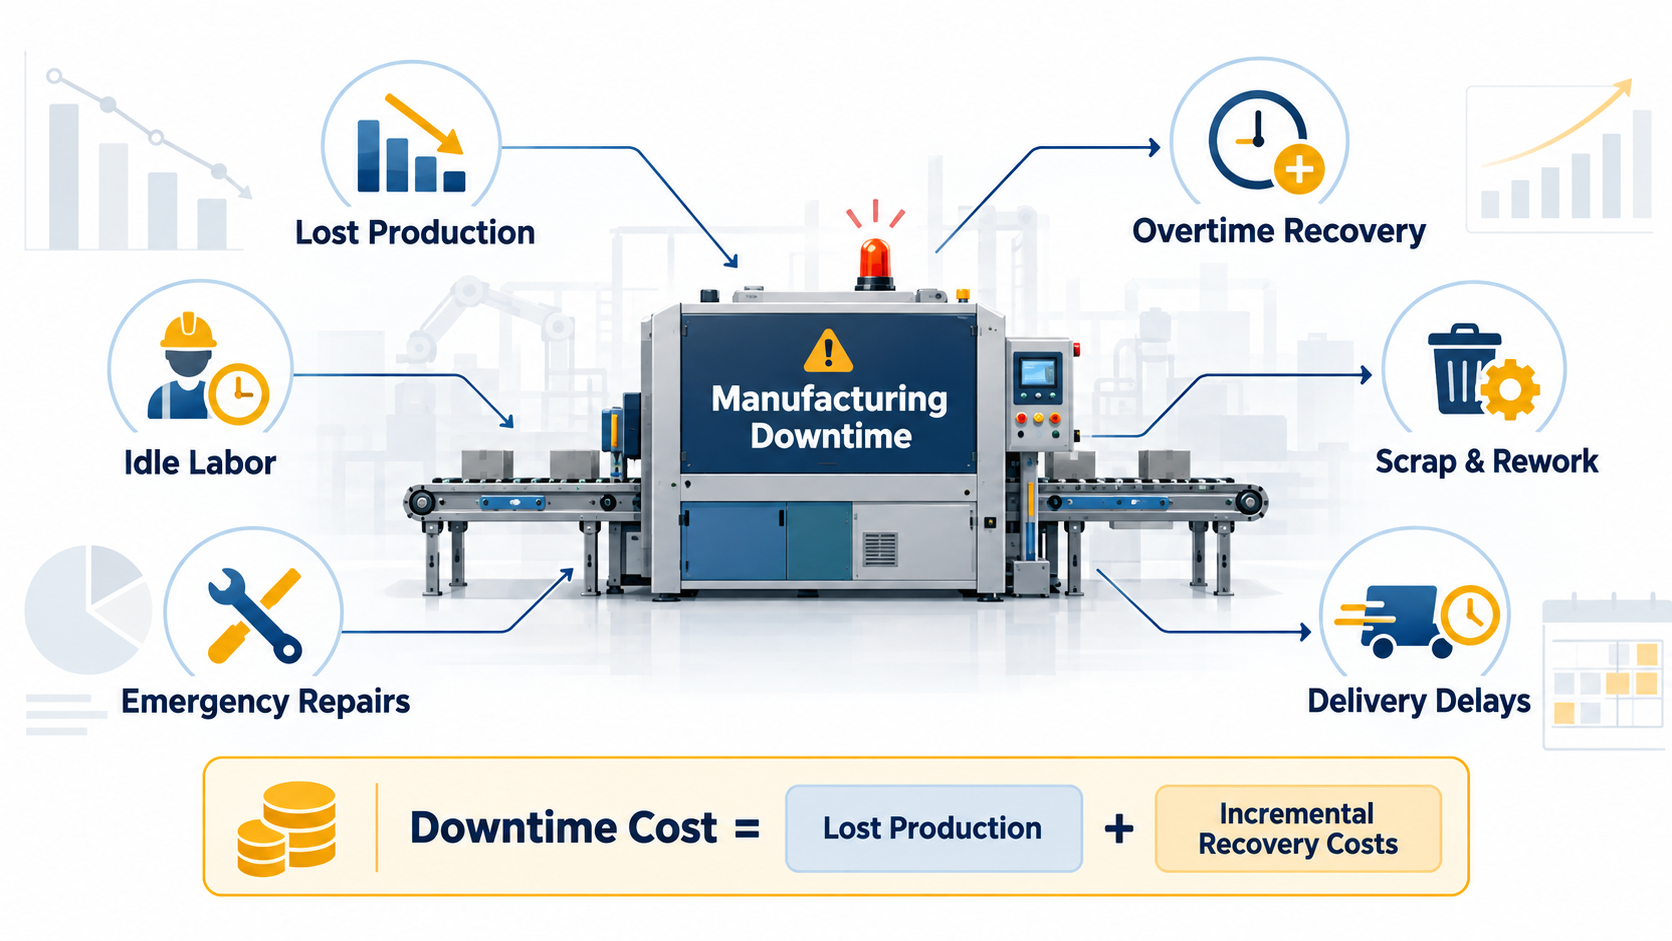
cost of manufacturing downtime

Understanding those losses turns downtime from a maintenance statistic into a business metric—and helps manufacturers decide which problems are worth solving first.

What Is the Cost of Manufacturing Downtime?

The cost of manufacturing downtime is the financial impact created when equipment, a production line, or a process cannot operate as planned.

Lost production is usually the most visible consequence. If a line normally produces 500 saleable units per hour and remains stopped for two hours, 1,000 units of scheduled capacity were lost during that period.

But that does not automatically mean the business lost the full selling price of 1,000 units.

If the production can be recovered later within normal available capacity, the financial impact may primarily consist of the additional costs required to catch up. If the plant is already capacity-constrained and those units cannot be recovered, the lost contribution from that production becomes much more important.

That distinction is essential. A useful downtime-cost calculation should reflect the economic impact of the interruption, not simply multiply stopped hours by sales revenue.

For manufacturers still establishing consistent measurement, a structured downtime tracking process provides the operational data needed to make these calculations meaningful.

What Costs Should Be Included in Manufacturing Downtime?

Lost output is only one part of the equation. Downtime can create costs across several areas of the operation.

Lost Production and Capacity

Every hour of downtime removes productive capacity from the schedule.

For a manufacturer operating close to capacity, those hours may translate directly into fewer saleable units. Even when the production can eventually be recovered, the interruption may displace other scheduled work or consume capacity that could have supported additional orders.

Repeated brief interruptions can be especially difficult to recognize. Individually they appear minor, but accumulated across shifts and production lines, micro downtime and small stops can consume a meaningful amount of available production time.

Idle and Disrupted Labor

Employees do not necessarily stop costing money when production stops.

Operators may wait for the process to resume, maintenance technicians may be pulled away from planned work, supervisors may coordinate recovery, and downstream employees may be unable to continue their own tasks.

Not every dollar of normal payroll should automatically be treated as an incremental downtime cost. But the loss of productive labor time is still operationally significant, particularly when recovery requires additional labor or overtime.

Emergency Maintenance and Repairs

Equipment failure can create costs well beyond the replacement part itself.

An unexpected breakdown may require:

  • emergency maintenance labor;
  • outside technicians;
  • expedited replacement parts;
  • maintenance overtime;
  • rescheduled preventive maintenance;
  • temporary equipment or workaround costs.

The production opportunity lost while the equipment remains unavailable may ultimately be much larger than the repair bill.

Overtime and Production Recovery

Lost production is often recovered rather than permanently abandoned.

But catching up may require an additional shift, longer operating hours, weekend work, or overtime. In that situation, the units are eventually produced, but the interruption still carries a financial cost.

This is one reason downtime can be underestimated: its effects often appear later in overtime or recovery budgets rather than being attributed to the original production stop.

Scrap, Rework and Restart Losses

Equipment problems do not always produce a clean stop.

Material may be trapped in the process when equipment fails. Restarting a line can generate additional scrap while settings stabilize. Equipment running outside normal conditions may also create quality problems before anyone recognizes that performance has degraded.

Scrap, rework, additional inspection, and restart losses therefore belong in the downtime-cost discussion when they were actually caused by the event.

Delayed Orders and Expedited Logistics

A production interruption can extend beyond the plant floor.

A missed schedule may require expedited freight, force production priorities to change, or threaten delivery commitments. Depending on the business, prolonged or repeated disruption can also contribute to contractual penalties or damaged customer relationships.

These costs are harder to quantify consistently, but that does not make them irrelevant.

How Does Downtime Affect Manufacturing Profitability?

Downtime affects profitability in two directions: it can reduce productive output while simultaneously creating additional expense.

More reliable production can help manufacturers:

  • protect available capacity;
  • meet schedules more consistently;
  • reduce emergency maintenance;
  • use labor more effectively;
  • limit scrap and rework;
  • reduce unnecessary overtime;
  • improve delivery reliability;
  • make better use of existing equipment before adding capacity.

But not every minute of downtime has equal financial value.

An hour lost on a lightly utilized machine with backup capacity may have little effect on total plant output. An hour lost at a bottleneck on a fully loaded production line may affect the entire operation.

That is why plant-specific economics matter much more than a generic “cost per hour” benchmark.

How Do You Calculate the Cost of Manufacturing Downtime?

A practical starting point is:

Downtime Cost = Lost Contribution From Unrecoverable Production + Incremental Costs Caused by the Stop

The calculation can be broken into four steps.

1. Measure the Downtime Event

Start with the operational facts:

  • Which machine, line, or process stopped?
  • How long was it unavailable?
  • How much production was affected?
  • Was the equipment a bottleneck or constraint?
  • Were downstream processes also affected?

Accurate duration and production context are the foundation of the calculation.

2. Estimate the Production Opportunity Lost

Calculate how much saleable production would normally have been produced during the interruption.

A useful working calculation is:

Potential Lost Contribution = Downtime Hours × Units per Hour × Contribution per Unit

Contribution per unit is more useful than selling price when estimating genuinely lost production because variable costs associated with units that were never produced may also have been avoided.

Then ask the critical question:

Can the lost production be recovered?

If another shift, machine, or available production window can recover it without displacing other valuable work, the full contribution should not automatically be treated as lost.

3. Add Incremental Costs Caused by the Event

Include additional costs that occurred because the stoppage happened, such as:

  • emergency repairs;
  • additional maintenance labor;
  • overtime;
  • expedited parts;
  • restart scrap;
  • rework;
  • outside contractors;
  • expedited freight;
  • contractual penalties.

Only count a cost once. A useful downtime model should clarify the economic impact rather than inflate it through overlapping assumptions.

4. Compare the Cost Across Events

The real value comes from applying the calculation consistently.

If one recurring failure costs approximately $500 per event and another costs $8,000, their improvement priorities should probably differ—even if the first problem occurs more often.

Combining financial impact with operational history allows manufacturers to rank problems more intelligently.

A Simple Manufacturing Downtime Cost Example

Suppose a production line:

  • stops for 2 hours;
  • normally produces 200 units per hour;
  • generates $15 contribution per unit;
  • cannot recover 50% of the lost production;
  • incurs $1,200 in additional repair, scrap, and recovery costs.

Potential lost output:

2 hours × 200 units = 400 units

Unrecoverable output:

400 × 50% = 200 units

Lost contribution:

200 × $15 = $3,000

Add incremental recovery costs:

$3,000 + $1,200 = $4,200 estimated downtime cost

The same two-hour event could cost much less if all production can be recovered normally—or substantially more if the stopped line is a bottleneck and customer orders are lost.

That is why the assumptions behind the calculation matter as much as the formula itself.

Why Industry Downtime Benchmarks Need Context

Industry figures can demonstrate the scale of unplanned downtime, but they are poor substitutes for a plant-specific calculation.

Siemens’ True Cost of Downtime 2024 reported that an hour of unplanned downtime among surveyed automotive manufacturers could reach approximately $2.3 million. Costs differed substantially across industries.

The useful takeaway is not that every manufacturer loses millions of dollars per hour.

It is that downtime economics vary dramatically according to production value, utilization, equipment criticality, available buffers, recovery capacity, labor requirements, and the consequences of delayed production.

Instead of asking:

“What does an hour of manufacturing downtime cost?”

ask:

“What does an hour of downtime on this specific process cost our operation?”

That produces a number manufacturers can actually use.

Downtime Data Is What Makes Cost Analysis Useful

Calculating downtime cost tells you how important a problem may be. It does not explain why it keeps happening.

For that, manufacturers need context around each event: machine, line, shift, duration, product, process, and reason for the stop.

When events are categorized consistently, recurring patterns become visible.

A plant may discover that one mechanical fault creates the greatest financial loss. Another may find that material shortages, changeovers, minor stops, or a specific shift consume more capacity than major equipment breakdowns.

Looking at manufacturing downtime data over time turns individual incidents into patterns that can be investigated and prioritized.

Prioritize Downtime by Impact, Not Duration Alone

The longest downtime event is not necessarily the most important.

Consider two problems:

  • Machine A fails for four hours twice a year.
  • Machine B stops for ten minutes several times every shift.

Machine A produces dramatic incidents. Machine B may quietly consume far more annual capacity.

The reverse can also happen. A short interruption at the plant’s primary constraint may cost more than many hours of downtime on noncritical equipment.

A stronger prioritization model therefore considers:

Frequency + Duration + Production Impact + Financial Impact

That prevents improvement teams from focusing only on whichever failures are most visible.

How Manufacturers Can Reduce the Cost of Downtime

The objective is not to eliminate every minute of downtime. Planned maintenance, cleaning, changeovers, and other scheduled activities are necessary.

The goal is to reduce avoidable loss and make necessary downtime more controlled.

A practical improvement cycle is:

Track → Categorize → Analyze → Prioritize → Correct → Verify

Track

Capture downtime consistently rather than relying on memory, handwritten notes, or only the most serious breakdowns.

Categorize

Use meaningful reason codes so the data explains why production stopped.

Analyze

Look for repeated events, machines, shifts, causes, and patterns. Frequency and cumulative duration often reveal problems that individual incidents hide.

Prioritize

Combine operational impact with estimated financial cost. Addressing the most expensive recurring losses can produce more value than simply attacking the longest stops.

Correct

Investigate the underlying cause and apply the appropriate maintenance, process, training, material, or operational response.

Verify

Continue measuring the same loss after corrective action.

Improvement should appear in the data—not simply be assumed because a repair or process change was completed.

For problems where rapid detection matters, real-time production monitoring can help teams recognize developing production issues sooner rather than discovering them only after reviewing historical reports.

Turn Downtime Into a Business Decision

Manufacturing downtime affects more than equipment availability.

It can influence production capacity, labor utilization, maintenance spending, quality, overtime, delivery performance, and profitability. The most expensive effects often appear somewhere other than the original maintenance bill.

The better approach is to connect operational downtime data with business impact:

  1. Measure what actually stopped.
  2. Determine how much production was affected.
  3. Separate recoverable production from genuinely lost opportunity.
  4. Add costs directly caused by the event.
  5. Compare recurring losses consistently.
  6. Focus improvement efforts where recovered capacity has the greatest value.

The goal is not simply to report fewer downtime hours.

It is to understand where productive capacity and profit are being lost—and which problems are worth fixing first.

Turn Downtime Losses Into Actionable Data

Thrive helps manufacturers automatically capture machine downtime and production context so teams can identify recurring losses, understand why equipment stops, and focus improvement efforts where they can have the greatest operational impact.

Request a demonstration to see how Thrive can help make downtime easier to measure, analyze, and reduce.

Sources & References

Micro Downtime in Manufacturing: How Small Stops Reduce OEE and Throughput

A two-minute jam may not seem serious. Neither does a 30-second sensor reset or a brief interruption to reposition material. But when the same small problem happens repeatedly throughout a shift, the lost production time can add up quickly.

These short, recurring interruptions are often described as micro downtime, micro stops, minor stops, or small stops. Because they are brief and frequently resolved by operators, they may never appear in traditional downtime reports. Yet they can reduce throughput, consume available capacity, and lower Overall Equipment Effectiveness (OEE).

The real challenge is not simply recognizing that small stops happen. It is measuring them well enough to understand how often they occur, what causes them, and which ones deserve attention first.

What Is Micro Downtime in Manufacturing?

Micro downtime refers to brief, recurring production interruptions that are too short to be treated like major equipment failures but collectively reduce output and equipment performance.

These interruptions are also commonly called micro stops, minor stops, or small stops.

Typical examples include:

  • Product jams that are quickly cleared
  • Blocked or misaligned sensors
  • Brief material-feed interruptions
  • Short machine resets
  • Product repositioning
  • Quick cleaning interruptions
  • Momentary upstream or downstream blockages

There is no universal time threshold for a micro stop. One plant may classify anything under a minute as a minor stop, while another may use a longer threshold.

What matters most is consistent classification. Manufacturers need a clear rule for when an interruption is treated as a small stop and when it becomes a conventional downtime event.

Micro Stops vs. Traditional Machine Downtime

Micro stops and conventional downtime both interrupt production, but they are usually measured differently.

Micro Stops Conventional Downtime
Typical duration Seconds to a few minutes Usually longer
Frequency Often high Typically lower
Resolution Often operator-cleared May require maintenance
Visibility Easy to overlook Usually obvious
OEE impact Commonly Performance loss Commonly Availability loss
Tracking need Machine or cycle-level data Standard downtime tracking

A 45-minute mechanical failure is hard to miss. A production line that stops for 60 seconds 25 times during a shift can lose nearly as much time without attracting the same attention.

That is why micro stops should complement—not replace—broader machine and equipment downtime tracking. Manufacturers need visibility into both major downtime events and the shorter interruptions that disappear inside normal production activity.

Why Small Stops Can Create Large Production Losses

One micro stop rarely looks important.

The problem is repetition.

Consider a production line experiencing 30 interruptions during a shift, with each lasting 90 seconds:

30 stops × 90 seconds = 45 minutes of lost production time.

That is three-quarters of an hour lost without a major breakdown ever occurring.

Repeated interruptions can also affect:

  • Production rhythm
  • Cycle consistency
  • Throughput
  • Operator productivity
  • Upstream and downstream equipment
  • Schedule attainment
  • Available manufacturing capacity

A short stop at a bottleneck machine can be particularly costly because its effect can spread across the line.

The bigger risk is that these interruptions become normalized. If the same jam or sensor issue happens every shift, operators may simply clear it and continue working.

What feels like a minor inconvenience can become a persistent production loss.

How Micro Stops Affect OEE

Micro stops are closely related to Overall Equipment Effectiveness (OEE) because they reduce the amount of productive work completed during scheduled production time.

OEE is based on:

Availability × Performance × Quality

Longer equipment stops generally reduce Availability.

Short recurring stops are commonly treated as Performance losses, especially when they fall below the manufacturer’s threshold for a recorded downtime event.

That means a plant can show relatively little traditional downtime while still losing substantial output through minor stops and reduced-speed operation.

This is why OEE becomes more useful when teams understand the losses behind the score. Thrive’s Overall Equipment Effectiveness resources explain the broader relationship between Availability, Performance, and Quality.

Common Causes of Micro Stops in Manufacturing

Micro stops can come from equipment, materials, controls, operating procedures, or interactions between machines.

Cause Typical Example
Material flow Misfeeds, jams, temporary shortages
Sensors Dirty, blocked, or misaligned sensors
Machine settings Incorrect settings or repeated resets
Product handling Misalignment or positioning problems
Upstream/downstream flow Brief starvation or blockage
Operator intervention Small manual adjustments
Cleaning Frequent quick cleaning interruptions
Equipment condition Minor recurring mechanical problems

The cause alone does not determine priority.

A problem that happens once per week may matter less than a 20-second interruption occurring 150 times per shift.

For micro stops, frequency and cumulative impact matter as much as individual duration.

Why Manual Downtime Tracking Often Misses Micro Stops

Traditional downtime tracking works best when an event lasts long enough for someone to notice, investigate, and record it.

Micro stops create a different problem.

An operator who clears a 25-second jam is unlikely to stop production again to document it. If similar interruptions happen dozens of times during a shift, manual logging becomes even less practical.

As a result:

  • Very short events may never be recorded
  • Operators may remember only larger interruptions
  • Repeated small stops can be grouped together
  • Different operators may classify the same event differently
  • Shift reports may show lower output without explaining why

Manual input can still be valuable for identifying causes, but high-frequency, short-duration events are easier to capture consistently with automated machine or cycle-level data.

How to Track Micro Downtime Accurately

Effective micro-stop analysis requires more than recording total lost time.

1. Define What Counts as a Micro Stop

Establish a consistent threshold based on the process, machine cycle, reporting needs, and how interruptions are handled.

2. Capture Machine States Automatically

Where possible, use PLC signals, machine controls, sensors, or other production data to detect when equipment moves from running to stopped.

Automatic detection reduces reliance on operator memory and makes it possible to capture interruptions that last only seconds.

3. Measure Duration and Frequency

Both matter.

One 20-minute stop and forty 30-second stops create the same amount of lost time, but they represent very different operational problems.

4. Add Operational Context

Machine data tells you that something happened. Context helps explain why.

Useful information can include the machine or line, shift, product or SKU, event category, production rate, and upstream or downstream conditions.

Once this information is collected consistently, it also needs to be presented in a way production teams can use. A well-designed manufacturing KPI dashboard can bring downtime, OEE, production performance, and other priority metrics into a more actionable operational view.

5. Look for Recurring Patterns

Ask which machines, causes, shifts, products, sensors, or material-handling points are repeatedly involved.

Patterns are usually more useful than individual events.

6. Separate Micro Stops From Slow Cycles

A micro stop means equipment temporarily stops.

A slow cycle means production continues, but below the expected rate.

Both can reduce OEE Performance, but they often require different corrective actions.

Which Micro Stops Should You Fix First?

Once micro-stop data becomes visible, manufacturers can uncover hundreds of individual events.

Trying to fix everything at once is rarely practical.

A useful prioritization approach is:

Frequency × Duration × Production Impact

The most frequent event is not always the most damaging. The longest event is not automatically the highest priority either.

Consider the cumulative loss and the role of the machine in the overall process. A recurring interruption at a bottleneck may have a much greater effect on throughput than the same problem elsewhere.

Historical analysis can also reveal whether losses are persistent, shift-specific, product-specific, or linked to particular operating conditions. Thrive’s article on manufacturing downtime data analysis looks more closely at how historical downtime information can uncover repeat problems and help prioritize improvement efforts.

How to Reduce Minor Stops and Keep Them From Returning

Once a high-impact micro-stop pattern is identified, the goal should be to understand why it keeps happening.

A practical improvement cycle is:

Identify → Observe → Find the Root Cause → Correct → Measure → Standardize

Corrective action might involve:

  • Sensor adjustment or relocation
  • Material-handling improvements
  • Machine-setting changes
  • Preventive maintenance
  • Equipment repair
  • Operator standard work
  • Better cleaning procedures
  • Production-line balancing
  • Training or process changes

After the change, continue measuring the same event.

If its frequency and cumulative lost time decrease, the improvement is working. If not, the investigation should continue.

This is where the value of production data becomes clearer: collecting information is only useful when it leads to better decisions and measurable action. Thrive’s article on turning downtime data into insight and action explores that broader continuous-improvement process.

Are Micro Stops Downtime or Performance Loss?

Micro stops are real production interruptions, but in OEE they are commonly treated as Performance losses rather than Availability losses when they fall below the manufacturer’s downtime-registration threshold.

That can seem contradictory because the machine did stop.

The distinction exists because OEE systems need a consistent boundary between major downtime events and very short interruptions.

The exact threshold matters less than applying it consistently across machines, shifts, and reporting periods.

Small Stops Shouldn’t Stay Invisible

Major breakdowns receive attention because they are impossible to ignore.

Micro stops are different. They may last only seconds, require little intervention, and disappear almost as quickly as they occur. That is exactly why they can become persistent sources of hidden production loss.

Once manufacturers can measure how often small stops occur, how long they last, where they happen, and what causes them, those interruptions stop being background noise.

They become measurable improvement opportunities.

Thrive helps manufacturers turn downtime and production data into clearer visibility so teams can identify recurring losses, prioritize problems, and measure improvement.

Industrial IoT (IIoT) in Manufacturing: Benefits, Challenges & How It Works

Manufacturing equipment produces a constant stream of information. Machine states, cycle counts, temperatures, production rates, equipment failures and operator observations can all reveal how production is performing. The challenge is collecting that information consistently and making it useful soon enough to act on it.

The Industrial Internet of Things (IIoT) helps solve that problem by connecting machines, sensors and software so operational data can be collected, communicated and analyzed with less dependence on manual reporting. But connecting equipment is only the beginning. The real value of IIoT in manufacturing comes from turning machine data into information that helps teams identify losses, respond to problems and make better production decisions.

What Is the Industrial Internet of Things (IIoT)?

The Industrial Internet of Things (IIoT) is the use of connected sensors, devices, machines and software to collect, exchange and analyze data in industrial environments. In manufacturing, IIoT connects activity on the plant floor with systems that monitor, store, analyze or visualize production information.

Instead of relying entirely on manual checks, isolated machine displays or end-of-shift reporting, manufacturers can gain a more continuous view of equipment condition and production performance. IIoT is closely associated with smart manufacturing and Industry 4.0, but its practical purpose can be straightforward: capture useful information from manufacturing processes and make it available to the people and systems that can act on it.

Common IIoT data points include machine running and stopped states, cycle counts, production output, downtime events, temperature, vibration, pressure, equipment condition, cycle time, energy use and quality-related process conditions.

The important question is not simply, “What can we measure?” It is, “What information will help us make a better operational decision?”

How Does IIoT Work in Manufacturing?

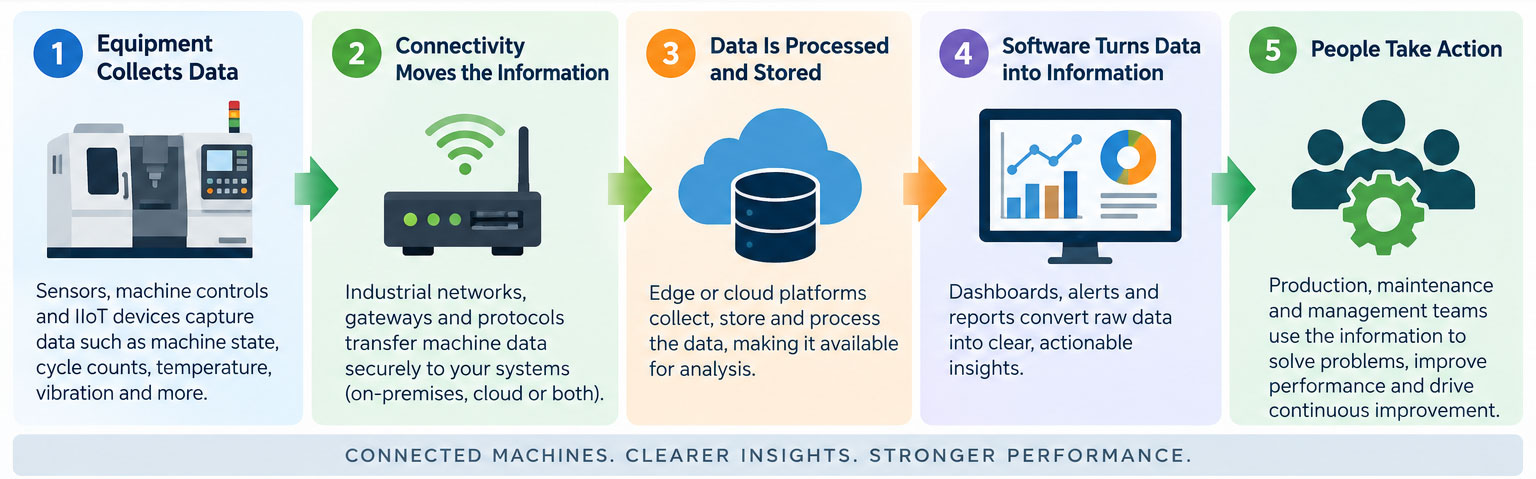
Most manufacturing IIoT systems follow the same basic path: physical equipment generates data, connectivity moves it, software processes it, and people or systems use the resulting information to take action.

  1. Equipment and sensors collect data. Information may come from machine controls, PLCs or sensors added to equipment to measure operating states and conditions.
  2. Connectivity moves the information. Industrial networks and gateways transfer selected machine data to systems where it can be processed, stored or analyzed.
  3. Edge or cloud systems process the data. Information may be processed close to the machine, in the cloud, on local infrastructure or through a hybrid architecture.
  4. Software turns data into usable information. Dashboards, alerts, reports and analytics help production, maintenance and management teams understand what is happening.
  5. People or systems take action. The information can support decisions about downtime, maintenance, production, quality and continuous improvement.

how-iiot-works-in-manufacturing


Common IIoT Applications in Manufacturing

IIoT becomes most valuable when it is tied to a specific production problem rather than treated as a technology project by itself.

Real-Time Production Monitoring

Connected equipment can provide current information about machine states, output and production activity. Supervisors can identify developing problems sooner instead of waiting for manually compiled reports. For a deeper look at how production information can be collected and distributed, see Thrive’s automated production reporting page.

Machine Downtime Tracking

IIoT can automatically detect when equipment stops and provide machine information that supports more accurate downtime records. However, knowing that a machine stopped is not enough. Manufacturers still need context such as duration, reason, frequency and operational impact. Thrive’s machine and equipment downtime tracking guide explains how that data becomes structured downtime information.

Condition Monitoring and Predictive Maintenance

Sensors can monitor variables such as vibration, temperature and pressure for changes that may indicate deteriorating equipment condition. When reliable data and maintenance processes are in place, this can support condition-based or predictive maintenance decisions before a problem develops into a larger failure.

Production Performance Analysis

IIoT data can help manufacturers examine cycle times, throughput, equipment utilization and other production measures across machines, lines and shifts. This creates a stronger evidence base for identifying bottlenecks and measuring improvement.

Quality and Process Monitoring

Connected sensors can track process conditions that influence product quality. When defects or process deviations occur, historical operating data can provide additional context for investigating what changed and where the problem originated.

Key Benefits of IIoT in Manufacturing

The benefits of industrial IoT in manufacturing do not come simply from connecting more equipment. They come from gaining better information and using it to improve operations.

Greater production visibility: Connected data can reduce blind spots between machines, shifts and production areas.

Faster identification of problems: Real-time information can make equipment stops and abnormal conditions visible sooner.

More consistent manufacturing data: Automated collection reduces dependence on handwritten logs, spreadsheets and operator recollection for information machines can capture directly.

Reduced downtime: Better visibility into equipment status, recurring stops and operating conditions can help teams identify sources of lost production.

Better maintenance decisions: Condition and failure data can help maintenance teams determine which assets require attention and why.

Stronger continuous improvement: Historical data provides a baseline for comparing performance before and after corrective actions.

The adoption of connected manufacturing technology is no longer limited to experimental projects. Deloitte’s 2025 Smart Manufacturing and Operations Survey of 600 executives at large manufacturers found that 46% were using IIoT solutions at the facility or network level, while 57% reported using cloud computing and 57% data analytics. The same survey reported average improvements of 10%-20% in production output and 10%-15% in unlocked capacity from smart manufacturing initiatives. Source: Deloitte, 2025 Smart Manufacturing and Operations Survey.

The Role of Cloud and Edge Computing in IIoT

Cloud software can provide a centralized environment for storing, analyzing and accessing manufacturing information without requiring every application to operate entirely on local plant infrastructure. This can make it easier to deploy specialized applications, view information from different locations and scale reporting across production areas or facilities.

Cloud computing is not the only option. Some manufacturing applications require local or edge computing because of latency, connectivity, bandwidth or operational requirements. Edge systems can process selected information close to the equipment, while cloud platforms can support broader storage, reporting and analysis.

For many manufacturers, the practical answer is a hybrid approach: process time-sensitive information locally while using cloud-based systems where centralized access, analysis and scalability add value.

Can IIoT Work With Older Manufacturing Equipment?

Yes. IIoT does not necessarily require replacing existing manufacturing equipment. This is an important distinction for plants with productive machines that were installed before modern connectivity became standard.

Depending on the equipment and the information required, manufacturers may be able to collect data through existing controllers and PLCs, industrial gateways, protocol converters or externally installed sensors. The right approach depends on what the machine already provides and what information is missing.

Before retrofitting a legacy machine, define the operational decision first. Is the goal to understand downtime, monitor equipment condition, improve production visibility or investigate quality? Connecting a machine without a defined use for its data can create more information without creating more value.

Common Challenges of Implementing IIoT

IIoT can improve manufacturing visibility, but implementation requires more than installing sensors. Several challenges repeatedly determine whether connected data becomes useful.

Integrating Different Equipment and Systems

Factories often contain equipment from different manufacturers, generations and control architectures. Creating consistent data across these systems may require gateways, protocol translation and careful integration between operational technology (OT) and information technology (IT).

Data Quality and Context

More data does not automatically mean better insight. A machine-state signal may show that equipment stopped, for example, but it may not explain whether the cause was a mechanical failure, changeover, material shortage, quality issue or operator intervention. Useful analysis depends on adding the right operational context.

Cybersecurity

Connecting industrial systems creates additional security considerations. Network architecture, access controls, device management and data security should be part of the implementation plan from the beginning rather than added after systems are connected.

Connectivity and Reliability

Manufacturing environments need dependable systems. Teams should consider what happens when network connectivity is interrupted, whether data must be buffered locally and which functions require local processing.

Cost and Scalability

The business case should be tied to a measurable operational problem. Attempting to connect every possible asset at once can add cost and complexity without proving value.

Workforce Adoption

Operators, maintenance teams, engineers and managers ultimately need to trust and use the information being generated. Technology that does not fit the workflow can produce large amounts of data without producing meaningful improvement.

Turning IIoT Data Into Action

Collecting manufacturing data is not the objective. The objective is to use that data to understand losses, prioritize action and measure whether changes improve performance.

A practical IIoT improvement cycle is: Collect → Contextualize → Analyze → Prioritize → Act → Measure.

For example, machine connectivity may reveal repeated short production stops. Downtime tracking can classify those events and determine their duration and frequency. Analysis can then show which causes account for the greatest production loss. The team can address the highest-priority cause and use the same data to determine whether the change actually reduced downtime.

That creates an operational feedback loop rather than simply a growing database of machine information.

How IIoT Connects With OEE and Continuous Improvement

IIoT data can also support broader manufacturing performance measurement. When reliable production, downtime and quality information is available, manufacturers can use it to understand availability, performance and quality losses more consistently.

That makes IIoT a useful data foundation for Overall Equipment Effectiveness (OEE), while OEE provides a framework for interpreting how effectively planned production time is being used. Thrive’s OEE tracking resource explains availability, performance and quality in more detail.

The distinction matters: IIoT connects and captures data; OEE and other improvement methods help manufacturers interpret performance and decide where improvement efforts should focus.

Getting Started With IIoT Without Overcomplicating It

Manufacturers do not need to connect an entire facility at once. A focused implementation can be easier to validate, easier for teams to adopt and easier to scale.

  • Start with a defined problem. Identify a measurable production, downtime, maintenance or quality issue.
  • Determine the data required. Decide which machine states, conditions or events are needed to understand that problem.
  • Use existing data where possible. Review PLCs, controls and existing sensors before adding new instrumentation.
  • Connect only what supports the objective. Avoid collecting data simply because it is available.
  • Give the data operational context. Define reason codes, thresholds, production standards or other information needed to interpret the signals.
  • Make the information visible to the right people. Dashboards and reports should support decisions, not just display metrics.
  • Measure the result before scaling. Prove that the use case produces useful insight or measurable improvement, then expand.

A focused example might be excessive unexplained downtime on a critical line. The required data could include machine state, stop duration and downtime reason. The objective would be to identify recurring causes and reduce lost production time. Once that process works reliably, the same approach can be extended to additional machines or lines.

How IIoT and Downtime Tracking Work Together

For manufacturers focused on production performance, IIoT and downtime tracking serve complementary roles. IIoT provides connectivity and machine data. Downtime tracking turns production interruptions into structured operational information.

Together, they can help manufacturers determine when equipment stopped, how long production was interrupted, which assets were affected, why downtime occurred, which causes recur most frequently and whether corrective actions improved performance.

Thrive helps manufacturers capture and analyze downtime and production information so teams can move from knowing that equipment stopped to understanding where production time is being lost and what deserves attention. The goal is not more data for its own sake; it is better visibility and better decisions.

Frequently Asked Questions About IIoT in Manufacturing


What does IIoT stand for?
IIoT stands for Industrial Internet of Things. It refers to connected sensors, machines, devices and software used to collect and exchange information in industrial environments.

What is the difference between IoT and IIoT?
IoT is the broader concept of connected devices exchanging data. IIoT applies connected technologies to industrial environments such as manufacturing plants, where equipment performance, reliability, production and operational conditions are central concerns.

Does IIoT require replacing existing manufacturing equipment?
No. Existing machines may be connected through controllers, gateways, protocol converters or additional sensors, depending on the equipment and the data required.

How can IIoT reduce manufacturing downtime?
IIoT can make machine states and operating conditions visible sooner and provide data for detecting and analyzing production interruptions. That information can support downtime analysis, maintenance and corrective action.

Is cloud software required for IIoT?
No. IIoT systems can use cloud, edge, on-premises or hybrid architectures depending on operational and technical requirements.

What should manufacturers track with IIoT?
Track the data that supports a defined operational decision. Common examples include machine status, cycle counts, downtime, output, temperature, vibration, pressure, energy consumption and process conditions.

From Connected Machines to Better Manufacturing Decisions
IIoT gives manufacturers the ability to collect operational information at a scale and speed that manual processes often cannot match. But connectivity alone does not improve production.

The real opportunity is to connect the right equipment, capture the right information and use that information to make better decisions. For manufacturers trying to reduce downtime, improve visibility and understand where production capacity is being lost, IIoT can provide the data foundation. Structured downtime tracking and production analysis can then turn that data into information teams can use to improve performance.

Manufacturing KPI Dashboard: What to Track and How It Should Actually Work

A manufacturing KPI dashboard is supposed to answer one question at a glance: how are we actually doing right now? In practice, a lot of dashboards fail at exactly that — either because they’re tracking the wrong things, showing the same view to everyone regardless of role, or updating so infrequently that “real time” is more of a suggestion than a fact.

What a Manufacturing KPI Dashboard Actually Is

It helps to separate two terms that get used interchangeably: metrics and KPIs. Metrics are any measurement you collect — cycle time, downtime minutes, scrap pieces, changeover duration. A KPI is a metric that’s specifically tied to a business objective you’re trying to hit. Downtime minutes is a metric; unplanned downtime as a percentage of scheduled time, tracked against a target, is a KPI.

A manufacturing KPI dashboard brings the KPIs that actually matter to your operation into a single visual view, updated close to real time, so decisions get made on current conditions instead of yesterday’s numbers.

The Metrics Most Dashboards Should Include

While every plant’s priorities differ, a handful of metrics show up on nearly every well-built manufacturing dashboard:

  • Overall Equipment Effectiveness (OEE) — availability, performance, and quality combined into one score
  • Unplanned downtime — the share of lost time that wasn’t scheduled or expected
  • Cycle time — actual time to produce a unit versus the standard or ideal time
  • First Pass Yield (FPY) — the percentage of units that meet spec without any rework
  • On-time delivery rate — how consistently production is hitting the schedule that downstream teams are counting on

The goal isn’t to track everything available — it’s to track the handful of numbers that are actually tied to a decision someone will make. A dashboard covered in metrics nobody acts on isn’t more useful; it’s just more cluttered.

A good rule of thumb: start from your current bottleneck, not a generic list. If your biggest constraint right now is unplanned downtime on one line, that line’s OEE and downtime causes deserve the most prominent spot on the dashboard — not because it’s the most impressive metric, but because it’s the one decision-makers will actually act on this week. As priorities shift, which metrics sit front-and-center should shift too.

Not All Dashboards Are Built the Same: Real-Time vs. Business Intelligence

Here’s a distinction that gets glossed over more than it should: a business intelligence (BI) dashboard and a true manufacturing KPI dashboard can look nearly identical on screen — both show charts, gauges, and trend lines — but they’re built on very different foundations.

A BI dashboard is often fed by a nightly or periodic data extract, which means what you’re looking at reflects yesterday’s conditions dressed up as today’s. A real manufacturing KPI dashboard, by contrast, is fed directly from the shop floor as events happen, which is the only way “real-time” actually means real-time rather than “recently updated.” If your dashboard is built on a batch process behind the scenes, an operator staring at it mid-shift isn’t actually seeing what’s happening on their line right now — they’re seeing a snapshot from hours ago with a live-looking interface layered on top.

One Dashboard, Different Views for Different Roles

A dashboard that tries to serve everyone identically usually ends up serving no one well. The information that matters to a plant director isn’t the same as what a line supervisor needs in the middle of a shift:

  • Operators and line supervisors need near-real-time, per-shift visibility — is the line on pace right now, and if not, why?
  • Plant managers need to see bottlenecks and quality issues across multiple lines, usually reviewed daily rather than minute-to-minute.
  • Executives care about higher-level trends — cost, throughput, and performance across the business — reviewed weekly or monthly rather than in the moment.

The best systems let all three views draw from the same underlying data, just filtered and paced differently, rather than requiring three completely separate reporting tools that never quite agree with each other. Mismatching cadence to role causes real problems: an operator forced to interpret a monthly trend chart mid-shift will ignore the dashboard entirely, and an executive drowning in per-minute machine states will do the same for the opposite reason. The fastest way to get a dashboard ignored company-wide is to give everyone the same view and hope it’s useful to all of them equally.

Scaling Across Multiple Locations

Everything above compounds once you’re managing more than one facility. A dashboard that only shows a single plant’s performance leaves you blind to the comparisons that matter most: which location is falling behind on the same product line, which plant can absorb more volume, and where a training gap or aging equipment issue is quietly dragging down results. Company-wide dashboards let you spot those patterns in a single view instead of manually compiling separate reports from each site and trying to compare them by hand.

What to Look for When Building or Choosing a Dashboard

  • Automated data connections. If someone has to manually update the dashboard, it isn’t really real-time — it’s a spreadsheet with better formatting.
  • Threshold-based alerts. A dashboard nobody is actively watching should still be able to notify the right person the moment something crosses a meaningful line.
  • Drill-down capability. The ability to go from a plant-wide number down to a specific line, shift, or machine is what turns a dashboard from a status report into a diagnostic tool.
  • Role-based views. Operators, supervisors, and executives shouldn’t be staring at the same screen expecting it to answer three different questions.
  • A manageable number of KPIs. The most common mistake in dashboard design isn’t showing too little — it’s showing too much. If every metric is on the screen, nothing on it stands out as urgent.

Frequently Asked Questions

How many KPIs should be on a manufacturing dashboard?
Fewer than you’d think. A dashboard with 20 metrics buried together makes it harder, not easier, to spot what actually needs attention. Most effective dashboards limit the primary view to a handful of KPIs tied directly to current priorities, with the option to drill into more detail as needed.

Is a manufacturing KPI dashboard the same as an OEE dashboard?
OEE is usually one of the most important KPIs on the dashboard, but a full manufacturing KPI dashboard typically covers more ground — downtime, cycle time, quality, and delivery performance alongside OEE, not instead of it.

How do I know if my dashboard is actually real-time or just looks like it?
Check where the data is coming from. If it’s pulled from a nightly extract or a periodic batch job, it’s a BI-style dashboard no matter how live the interface looks. A genuinely real-time dashboard is fed directly from machine and shop-floor data as events happen.

Why do people stop looking at their dashboard after a few weeks?
Usually because it wasn’t built around a decision they actually make. A dashboard that shows the same generic KPIs to everyone, regardless of role or current priorities, tends to get ignored fastest — the fix is narrowing what’s shown to what’s genuinely actionable for the person looking at it.

Want a dashboard that’s actually built on live shop-floor data, not a batch extract dressed up to look real-time? See how Thrive’s dashboard works, or learn more about automated production reporting.

Manufacturing Downtime Data Analysis: Turning History Into Fewer Repeat Problems

Collecting downtime data is only the beginning.

The real value appears when manufacturers analyze that information to understand why production keeps stopping, which losses have the greatest impact, and where corrective action is most likely to improve performance.

That is the purpose of manufacturing downtime data analysis. Downtime tracking tells you what happened. Analysis turns those recorded events into patterns, priorities, and decisions that can help prevent the same losses from repeating.

What Is Manufacturing Downtime Data Analysis?

Manufacturing downtime data analysis is the process of examining recorded production stoppages to identify recurring losses, compare their impact, understand patterns, and determine where improvement efforts should be focused.

A useful downtime record typically answers several basic questions:

  • What machine or line stopped?
  • When did the event begin and end?
  • How long did it last?
  • Why did it happen?
  • How often does the same problem occur?
  • What production was lost as a result?

Capturing those events accurately is the foundation. Thrive’s broader guide to machine and equipment downtime tracking explains how manufacturers can build that underlying visibility.

Analysis begins once the data has been collected consistently enough to compare events over time.

The Data You Need Before Analysis Becomes Useful

More data does not automatically produce better decisions.

What matters is collecting information that helps answer a specific operational question.

At minimum, useful downtime analysis normally requires:

Data Point What It Helps Explain
Machine or production line Where the loss occurred
Start and stop time When it happened
Duration How much production time was lost
Reason or category Why production stopped
Frequency Whether the problem is recurring
Shift or operating context When or under what conditions it occurs

Additional context such as product, SKU, operator, production rate, maintenance activity, or upstream/downstream conditions can make the analysis more useful when those factors affect the process.

This is one advantage of automatic machine-state capture. Instead of relying entirely on someone to remember when a stop began or how long it lasted, the system can establish the event automatically while operators provide the context that machine signals alone cannot explain.

The Metrics That Make Downtime Data Easier to Compare

Raw downtime minutes are useful, but they rarely tell the entire story.

Several measurements help manufacturers compare losses more meaningfully.

Downtime duration shows how much production time a particular event or category consumed.

Downtime frequency shows how often the problem occurs. A recurring two-minute stop can eventually create a larger loss than a single long breakdown.

Downtime percentage compares lost time with scheduled production time, making it easier to compare equipment or shifts that operate for different amounts of time.

Mean Time to Repair (MTTR) shows how long equipment typically remains unavailable once a failure occurs.

Mean Time Between Failures (MTBF) helps indicate how frequently equipment experiences failures.

The right metric depends on the problem being investigated. A maintenance team may care strongly about MTTR and MTBF, while a production manager may need to understand lost throughput by line, shift, or product.

A broader manufacturing KPI dashboard can bring these downtime measures together with the other KPIs needed to understand current manufacturing performance.

Categorizing Downtime So the Analysis Means Something

Even sophisticated analysis becomes unreliable when similar events are categorized differently.

This is why downtime reason codes and consistent event categories matter.

Typical categories might include:

  • Mechanical failure
  • Electrical problems
  • Material shortages
  • Changeovers
  • Cleaning
  • Scheduled maintenance
  • Quality problems
  • Operator-related interruptions

Manufacturers should also separate planned downtime from unplanned downtime.

Planned downtime includes activities such as scheduled maintenance, cleaning, or expected changeovers. Unplanned downtime includes breakdowns, unexpected shortages, faults, and other interruptions that were not part of the production plan.

The purpose of categorization is not to create as many reason codes as possible. It is to create enough consistency that similar events can be grouped and compared.

If one shift records an event as a changeover while another calls the same event machine downtime, trend analysis quickly becomes misleading.

A Practical Downtime Analysis Process

Once reliable event data exists, manufacturers can move through a relatively simple analysis cycle.

1. Group Similar Events

Start by organizing downtime according to relevant categories such as machine, line, reason code, shift, product, or failure type.

This prevents a single plant-wide downtime number from hiding where the losses are actually occurring.

2. Compare Frequency and Duration

Look at both how often a problem occurs and how much time it consumes.

For example:

  • one mechanical failure lasting 60 minutes;
  • twenty material-feed interruptions lasting three minutes each.

Both create one hour of downtime, but they represent very different problems.

This is especially important for high-frequency short interruptions. Thrive’s article on micro downtime in manufacturing looks specifically at how recurring small stops can remain hidden while reducing throughput.

3. Rank the Largest Losses

A Pareto-style analysis can help rank downtime categories according to total impact.

Instead of trying to solve every recorded problem simultaneously, manufacturers can identify the handful of causes responsible for the greatest amount of lost production.

Frequency should not be viewed in isolation, though. The most common event is not necessarily the most damaging.

Useful prioritization considers:

Frequency × Duration × Production Impact

An interruption affecting a bottleneck machine may deserve greater attention than the same amount of downtime on equipment with excess capacity.

4. Drill Into the Pattern

Once a significant loss is identified, break it down further.

Ask:

  • Does it happen mostly on one machine?
  • Is one shift affected more than another?
  • Does it occur with a particular product?
  • Is its frequency increasing?
  • Does it happen during startup or changeover?
  • Are upstream or downstream conditions involved?

This is where historical data begins turning a general statement such as “we have too much downtime” into a much more useful question such as:

Why is Line 3 repeatedly losing production to material-feed interruptions during the second shift?

5. Investigate the Root Cause

Downtime analysis identifies where the biggest recurring problem is.

It does not automatically prove why that problem exists.

Once the analysis isolates a high-impact pattern, teams can investigate the underlying cause using maintenance knowledge, operator observations, process review, or structured root-cause methods.

For example, repeated sensor-related downtime may ultimately result from contamination, alignment, vibration, incorrect settings, product positioning, or another process condition.

The data focuses the investigation. The investigation identifies the cause.

6. Take Corrective Action and Keep Measuring

Analysis should end with action—not another report.

Depending on the cause, corrective action might involve:

  • equipment repair;
  • preventive maintenance;
  • machine-setting changes;
  • material-handling improvements;
  • operator training;
  • staffing adjustments;
  • revised changeover procedures;
  • process changes.

After implementing the change, continue measuring the same loss.

If event frequency and lost production decrease, the data provides evidence that the corrective action worked.

That closes the loop:

Data → Pattern → Priority → Root Cause → Corrective Action → Measurement

Historical Analysis and Real-Time Monitoring Solve Different Problems

Historical downtime analysis and real-time production monitoring are complementary rather than competing approaches.

Real-time monitoring helps manufacturers respond to what is happening now.

Historical analysis helps answer:

  • What keeps happening?
  • Which problems are getting worse?
  • Which improvements actually lasted?
  • Which machines or shifts consistently lose the most production?

A real-time alert can help the team react to today’s stoppage.

Historical data can reveal that the same stoppage has occurred 37 times during the past month.

Both forms of visibility are useful, but they answer different questions.

How Often Should Downtime Data Be Reviewed?

The appropriate review cadence depends on the type of decision being made.

Some information should be visible immediately. Production teams may need to know about a current interruption within minutes.

Pattern analysis can operate on a different cadence.

Daily or weekly reviews can help teams identify emerging recurring problems, while longer monthly or quarterly trends can reveal equipment deterioration, persistent process losses, and whether improvement initiatives are producing sustained results.

The important point is not to wait so long that obvious repeat problems continue for weeks before anyone examines the pattern.

Common Downtime Analysis Mistakes

Several problems can make downtime analysis less useful than it should be.

Analyzing inconsistent data.
If categories and reason codes are applied differently from one shift to another, comparisons lose meaning.

Looking only at total downtime.
Plant-wide totals can hide the machines, shifts, products, or causes responsible for the loss.

Looking only at frequency.
The most common stop is not automatically the most expensive one.

Ignoring short interruptions.
Small recurring stops can accumulate into significant production losses even when no major failure occurs.

Collecting data without acting on it.
A dashboard or report creates little value if nobody owns the next investigation or corrective action.

Making a change without measuring the result.
Without continued tracking, teams cannot know whether a fix actually reduced the original loss.

Turning Downtime History Into Better Decisions

A downtime tracking system can tell manufacturers that production stopped.

Downtime analysis explains what deserves attention next.

By comparing event frequency, duration, reason, equipment, shifts, and production impact, manufacturers can move beyond isolated incidents and start identifying recurring patterns.

The goal is not to generate more reports.

It is to create a repeatable improvement process:

capture reliable data → identify the largest losses → investigate why they occur → take action → measure whether the loss decreases.

For manufacturers that want downtime and production information collected automatically rather than reconstructed after the fact, Thrive combines downtime tracking with automated production reporting to give production teams clearer visibility into what is happening and how performance changes over time.

Real-Time Production Monitoring: Catch Problems Before They Cost You a Shift

Most manufacturers aren’t short on data — they’re short on timely data. Machines are generating signals constantly, but if that information only reaches a person at the end of a shift, it’s already too late to act on the problem it describes. Real-time production monitoring closes that gap, giving you an accurate picture of what’s happening on your shop floor at the exact moment it’s happening.

What Real-Time Production Monitoring Actually Means

Real-time production monitoring is the continuous tracking of machine states, output, and performance as it occurs – not a summary compiled after the fact. Instead of waiting for someone to notice a bottleneck and write it down, sensors and connected systems capture the event immediately and make it visible right away.

The distinction from historical reporting matters here: historical data tells you what already happened and helps you spot trends over time, while real-time monitoring tells you what’s happening right now, while there’s still time to respond. A strong operation needs both – but real-time visibility is what lets you catch a problem in the moment instead of reading about it tomorrow.

Machine Monitoring vs. Production Monitoring

These two terms get used interchangeably, but they describe different layers of the same system. Machine monitoring is the foundational layer – automated, real-time data collection from individual pieces of equipment (often the process constraint) that builds an accurate record of what each machine is actually doing.

Production monitoring sits on top of that foundation. It takes the raw machine data and turns it into something people can actually use to make decisions – reviewing performance within a structured framework, spotting where output is falling behind plan, and taking action based on what the data shows. In short: machine monitoring builds the data; production monitoring puts it to work.

How Real-Time Data Gets Collected

There are a few common ways manufacturers capture this data:

  • Direct machine integration — communicating with a machine’s existing controller to pull data with no additional hardware needed.
  • Added sensors or PLCs — for equipment that doesn’t already report data on its own, an inexpensive sensor or PLC can be added to capture run/stop/error states.
  • IoT-connected devices — increasingly common on newer equipment, these stream data continuously to a cloud-based dashboard without requiring a dedicated server on-site.

Whichever method you use, the goal is the same: get machine state, part counts, and downtime events into a system that updates continuously, not one that waits for someone to log in and refresh a report.

The Metrics Worth Watching in Real Time

Not all data is equally useful moment-to-moment. The metrics that matter most in a real-time context are the ones tied directly to whether a line is on pace right now:

  • Machine uptime vs. downtime — the most immediate signal that something needs attention.
  • Units produced vs. plan — tells you whether you’re on track to hit a shift or daily target while there’s still time to course-correct.
  • Overall Equipment Effectiveness (OEE) — availability, performance, and quality combined into a single score.

That last point matters more than it might seem: OEE calculated from delayed or incomplete data is only as accurate as the data behind it. If downtime events are logged hours late or categorized inconsistently between shifts, your OEE score reflects guesswork, not reality — which means decisions based on it are only as good as the data feeding them.

Why Real-Time Visibility Changes Behavior on the Floor

One of the most underrated benefits of real-time monitoring isn’t the data itself — it’s what visibility does to accountability. When operators can see their own line’s performance updating live, rather than finding out how they did at the end of the day, it naturally shifts behavior. People catch small issues before they compound, and it becomes obvious — to operators and supervisors alike — who might need a bit more training on a specific piece of equipment or process.

This works both ways: it also surfaces which operators are consistently performing well, giving you real, current information rather than a gut-feel impression formed weeks ago.

Turning Live Data Into Something Usable

Collecting real-time data is only valuable if someone can actually interpret it quickly. This is where dashboards and visual displays do the heavy lifting — translating a stream of raw numbers into a chart, gauge, or Pareto view that shows, at a glance, whether a line is on pace and what’s causing the biggest losses when it isn’t.

Many real-time systems also support automated alerts — a notification sent the moment a machine goes down or a threshold is crossed, rather than requiring someone to be staring at a dashboard at the right moment. That combination of visual clarity and proactive notification is what actually makes real-time data actionable instead of just available.

What to Look for in a Real-Time Monitoring System

  • No dependency on manual entry. If someone still has to type in downtime reasons after the fact, you haven’t actually achieved real-time visibility.
  • Compatibility with the equipment you already have. A system that requires replacing legacy machines to get connected isn’t practical for most plants — look for sensor or PLC options that work with older equipment.
  • Alerts, not just dashboards. A screen nobody is watching doesn’t help; look for systems that can push notifications to the right person when something needs attention.
  • Simple, accessible reporting. The best real-time systems present information in a way that doesn’t require training to interpret — if your team needs a manual to read the dashboard, it’s working against you.

Frequently Asked Questions

Is real-time production monitoring the same as automated production reporting?
They’re closely related. Automated production reporting is the broader system — capturing and distributing data on downtime, output, and performance. Real-time monitoring specifically refers to seeing that data the moment it happens, rather than in a scheduled report.

Do I need to replace my existing equipment to get real-time monitoring?
No. Most systems can connect to a machine’s existing controller directly, or use an added sensor or PLC for older equipment that doesn’t already communicate on its own.

How does real-time monitoring affect my OEE score?
It makes the score more accurate. OEE calculated from delayed or manually logged data reflects guesswork as much as reality; real-time data capture removes that gap.


Want to see what real-time visibility looks like on your own shop floor? Explore Thrive’s downtime tracking system or learn more about automated production reporting.

The Benefits of OEE (Overall Equipment Effectiveness) — and How to Actually Capture Them

Overall Equipment Effectiveness distills three things that matter most on your shop floor – availability, performance, and quality – into a single score. A perfect 100% means you’re manufacturing only good parts, as quickly as your equipment allows, with zero stop time. Nobody actually hits that number, and that’s fine – OEE isn’t a scoreboard you’re trying to max out. It’s a diagnostic tool, and the real benefits show up in what you do with what it tells you.

The Core Benefits of Tracking OEE

The most immediate benefit is visibility: instead of a vague sense that “the line isn’t running as well as it should,” you get a specific breakdown of why. Unlike watching a handful of isolated KPIs – throughput here, cycle time there, changeover time somewhere else – OEE combines everything into one number that exposes losses none of those individual metrics would catch on their own. That specificity pays off in a few concrete ways:

  • Downtime becomes a dollar figure, not a feeling. Once you know your line’s throughput and margin per unit, a few points of lost availability translates directly into a number leadership can act on. If a line runs 200 units an hour at a $12 margin, a 3-point drop in OEE has a specific, calculable revenue impact – not just an unlogged sense that “we lost some time today.”
  • Quality issues get caught earlier. Pinpointing when and where defects happen – including parts that end up needing rework – means you can fix the underlying cause before it produces a pile of rejected parts, rather than discovering the problem after the fact.
  • You stop guessing where to focus. Because OEE separates loss into three distinct buckets, it tells you where your next improvement project should actually start – rather than everyone independently guessing, or worse, competing for attention on separate KPIs.
  • Maintenance and operations start speaking the same language. A drop in availability tends to point to maintenance; a drop in performance often sits with operations; quality can span both. Sharing one number means the conversation about what’s dragging performance down happens with data instead of blame.

Reading Your OEE Score: A Diagnostic, Not Just a Number

One of the more underused benefits of OEE is what the shape of your three sub-scores tells you, beyond the overall percentage. If availability is weak but performance and quality are solid, that usually points to downtime or slow changeovers. If availability and quality are fine but performance lags, you’re probably looking at speed loss – worn tooling, conservative settings, or an aging asset. If both availability and performance are strong but quality is the outlier, that’s typically process drift or a setup issue.

This matters because the score by itself is only a diagnosis. The actual benefit – reduced downtime, lower repair costs, higher-quality output – only materializes once that diagnosis triggers a specific fix. A team that tracks OEE meticulously but never acts on what it reveals will have cleaner reports and the exact same production problems a year later. The more mature version of this is closing the loop entirely: when a stop is detected, the right person gets notified immediately, rather than the event sitting in a report that gets reviewed days later. Shrinking the gap between “something went wrong” and “someone is fixing it” is where a lot of the compounding value of OEE actually lives.

Common Mistakes That Blunt These Benefits

A surprising amount of the value of OEE gets lost before it ever reaches a decision-maker, and it’s worth naming the usual culprits directly:

  • Measuring over too short a window. Pulling OEE data from a single shift, or even a single day, doesn’t tell you what “normal” looks like for your line – one unusually long downtime event can skew the number into something meaningless. A month or more of data gives you enough of a baseline to separate a real trend from ordinary variation.
  • Relying on manual data entry. Operators jotting down stop times on paper or in a spreadsheet is slow, easy to skip during a busy shift, and prone to the kind of human error that makes an OEE score more fiction than fact. A short stoppage that felt too minor to log still counts, and enough of those add up to a genuinely misleading number.
  • Underestimating the small stuff. Minor stops, slight speed reductions, and small defects rarely look significant in the moment, but they accumulate over a shift or a week into some of the largest losses on the line – often larger than the one big breakdown everyone remembers.
  • Rolling it out without buy-in. If operators and supervisors see OEE tracking as something being done to them rather than a tool that makes their job easier, adoption stalls regardless of how good the software is. Showing the team a clear, early win tends to do more than any policy memo.

Why Automation Is Where the Real Benefit Starts

Every mistake above gets easier to avoid once data capture is automated instead of manual. Automating that capture removes the guesswork and frees your team to spend their attention on actually fixing problems instead of documenting them. It’s also worth pairing automated data collection with a bit of human context: encouraging operators to log a quick note when something unusual happens (what caused it, what they tried) preserves the “why” behind the numbers in a way raw timestamps never will – and that historical context becomes genuinely valuable the next time a similar issue shows up.

The best OEE tools also make the resulting data usable by anyone, not just whoever built the spreadsheet. A good manufacturing KPI dashboard turns raw numbers into something a plant manager, a maintenance lead, and an operator can each look at and immediately understand – which matters because the whole point of automating this is to get insight in front of people faster, not just to collect cleaner data for its own sake.

Getting the Full Benefit Means Implementing OEE Across Your Entire Line

A common mistake is treating OEE as something that only applies to your handful of “critical” machines. That leaves you with a partial picture – you know how your headline assets are performing, but you’re blind to the compounding losses happening on everything else. The real value of OEE compounds when it’s implemented plant-wide: you can compare shift-to-shift efficiency, break performance down by SKU, and even compare performance across multiple locations if yours is a larger operation.

It also helps to have one point of ownership – ideally a single person who’s already respected on the floor, comfortable working with data, and given the standing responsibility of monitoring the trend and pushing improvements – rather than leaving it to whoever happens to notice a problem that day. The tool itself should support that person, not create more work for them: if a system requires a small team of specialists to interpret its output, it’s adding a layer of friction that works against the whole point of tracking OEE in the first place.

What a “Good” OEE Score Actually Looks Like

It’s worth setting realistic expectations here. World-class OEE performance generally sits around 85%, and most manufacturing operations start out well below that mark. That’s not a discouraging fact – it just means there’s real room to improve almost everywhere, and a lower starting score isn’t a sign that something is broken. It’s the normal starting point for the work OEE is meant to guide, and consistent, incremental progress toward that number matters far more than hitting any particular figure quickly.

One Honest Caveat

OEE is genuinely one of the best tools available for understanding shop-floor productivity, but it isn’t a silver bullet. Leaning on it too heavily, without keeping sight of customer needs or the broader production context, can occasionally push a team toward decisions that look good on the OEE score but don’t actually serve the business – for example, optimizing machine utilization at the expense of flexibility a customer actually needs. Used well, OEE is a guide for where to look next, not the only number that matters.

Ready to Get More Out of Your OEE Score?

Understanding the benefits of OEE is one thing – actually capturing them requires accurate, automated data you can trust. Thrive’s downtime tracking and OEE reporting tools are built to remove the manual guesswork so your team can spend their time on fixes, not paperwork. Schedule a demo to see it in action.

Want to Reduce Your Production Costs? Improve Your OEE Score  

Regardless of the industry that you’re operating in, manufacturers are always looking for opportunities to cut costs without sacrificing quality. This is especially true as many industries like pharmaceuticals and even food and beverage become increasingly competitive all the time.

Thankfully, there is already an opportunity to do precisely that – it’s just one that far too few business leaders are currently taking advantage of. It’s called Overall Equipment Effectiveness or OEE and it brings with it a host of different opportunities to cut costs that are absolutely worth a closer look.

The Key to Greater Efficiency is Here

To truly get an understanding of how your OEE score impacts your production costs, you must first begin to think about those costs as more than just line items on a balance sheet somewhere. Yes, producing X number of parts costs Y dollars per part – but it’s also a great deal more sophisticated than that.

When you improve your OEE score, you make meaningful gains towards eliminating unplanned downtime and reducing unnecessary stops. You learn the actionable information you need to make the types of changes that will improve line changes and retooling techniques. In other words, you boost availability – something that will allow you to produce more parts without necessarily adding resources like new equipment.

Speaking of that equipment, improving your OEE score also means that you’re improving not only the performance of that which you’re already working with, but the utilization as well. It helps guarantee that all machines are operating at their maximum potential – or at least as close to it as you can get. This, too, helps realize the full potential of your existing infrastructure, thus cutting costs significantly along the way.

Not to mention the fact that if you have a high OEE score, it means that you’re doing your part to avoid poor quality parts that need to be rejected as soon as they come off the assembly line. It means that you’re avoiding going through unnecessary procedures just to arrive at a less-than-desirable conclusion.

When taken together, all of this means a few important things. Your OEE score is a direct indication of how much waste you currently have in your manufacturing process and the more you can eliminate, the easier it becomes to produce A) high quality parts and other components B) as quickly as possible. Once you get to that point, you can start to see the highest possible return on investment of the materials you’re working with, the machines you’re using and even the people you’ve paid to run them – which in and of itself is the most important benefit of all.

If you’d like to find out more information about how improving your OEE score can help significantly reduce your production costs over time, or if you just have any additional questions you’d like to discuss in a bit more detail, please don’t hesitate to contact Thrive today.


How to Extract as Much Value From Your OEE Score as Possible  

Overall Equipment Effectiveness or OEE is one of the most important metrics for manufacturers in the modern era. However, it’s so much more than just a simple number. To truly get as much insight from it as possible, you need to understand what that value actually means. Getting to that point requires you to have an essential context surrounding what you’re measuring and, more importantly, why it matters that you’re paying attention to these qualities to begin with.

What the Data is Really Trying to Tell You

To truly get a sense of what your OEE score is revealing about your operations, you need to come to a greater understanding of how this score is calculated in the first place.

Consider your quality score, for example. Let’s say you produced 20,000 parts in a given period, but had to eliminate 5,000 due to issues with their viability. 20,000 parts minus 5,000 would be 15,000 which, when divided by that original 20,000 production run, would equate to a quality score of roughly 75%.

Now, to be fair – this is not a bad score at all. It’s not necessarily possible to reach an OEE score of 100%, as that would mean that everything was operating at total efficiency – a tall order, to be sure. But it does indicate that there is room for improvement in terms of the quality of your output and once you know that you have the starting point of something far more important.

Unplanned stops could be an issue, for example – those periods where key pieces of equipment fail, when an operator isn’t available to run a machine or when unplanned maintenance takes place. It could even be an issue with planned stops – shift changes are taking too long, machines aren’t being as cleaned as quickly as they should be, etc.

Regardless – once you know that you have an issue, and once you know what it is, you have the actionable information you need to fix it. This, in essence, is what OEE is all about.

All told, OEE is the gold star metric for manufacturing organizations – but looks can be deceiving. Don’t necessarily assume that you can get to a score of 100%, because you can’t. Nobody does. But even if you come out of the gate with a low score, so long as it is always ticking upwards you can be confident that you’re moving in the right direction. Once you hit a score of 85% or above, you can rest easy knowing that you’re doing everything you should be – which is the most important thing of all.

If you’d like to find out more information about how to extract as much value from your OEE score as possible, or if you just have any additional questions that you’d like to see answered in a bit more detail, please don’t delay – contact the team at Thrive today.


Want to Learn More From Downtime Tracking? Pay Attention to These Key Attributes  

At its core, downtime tracking doesn’t just help you better understand the current state of the equipment in your manufacturing facility. It also helps you gain visibility into what that equipment is capable of, and what the potential is when you get as close to peak productivity as possible.

The more information you’re tracking, the more insight you have – and the better choices you can make in terms of optimization.

According to one recent study, it’s estimated that about 70% of all organizations don’t actually know the full extent of their unplanned downtime events. They may know that they have an issue, but they’re not sure why – which means they can’t prevent it from happening again.

Thankfully, downtime tracking solutions like those available from Thrive can help relieve that issue – provided that you pay attention to a few key attributes along the way.

Harnessing Downtime Tracking to Your Advantage

To make sure that you’re deriving the most value from your downtime tracking software, you need to be as detailed in terms of your downtime data collection as possible. This means that in addition to capturing the process area or specific line where the downtime event occurred, you also need to make a note of things like the machine itself as well.

Equally important are things like the product that was being worked on at the time of the event. Sometimes, it’s not so much a matter of an issue with the machine as it is an issue with the process itself.

Of course, the length of the event is also paramount to helping better understand what is going on. If you know when an event happened and when it was eventually corrected, you should be able to see this number get shorter over time as you make steps to improve. Operator comments will be equally important to that end, as they can help provide additional insights into an event including what the conditions were and what steps were taken to ultimately fix the problem.

Overall, downtime tracking is about painting a more complete picture than you can arrive at on your own. It’s not just about what happened – it’s about who was involved, when the event occurred and where it took place. All of these help answer the most crucial question of all: “why is this issue happening?” Is it a one-time affair, or is it recurring? What is the context surrounding the issue? Once you’re able to answer those questions, you have nearly everything you need to emphasize continuous improvement across your manufacturing lines – leading to greater efficiency and even greater profits as well.

If you’d like to find out more information about the key attributes that you should be paying attention to in order to get the most out of your downtime tracking efforts, or if you’d like to speak to someone about your own needs in a bit more detail, please feel free to contact Thrive today.